RAG chatbots use document retrieval, embeddings, vector search, prompts, and a language model to assemble answers from selected passages; one workflow appends retrieved passages to GPT-4’s input. RAG Chatbot Mistakes That Lead to Wrong Answers usually require checking retrieval, context, grounding, and generation separately rather than changing the model blindly.
- A RAG workflow appends retrieved passages to a language model’s input to generate an informed response.
- Approximate nearest-neighbor search trades perfect recall for speed.
- Context Precision accounts for the rank position of each retrieved chunk.
- A test workflow can run questions and log answers, retrieved chunks, and evaluator scores for each configuration.
How does a retrieval-augmented generation (RAG) chatbot use retrieved documents to answer a question?
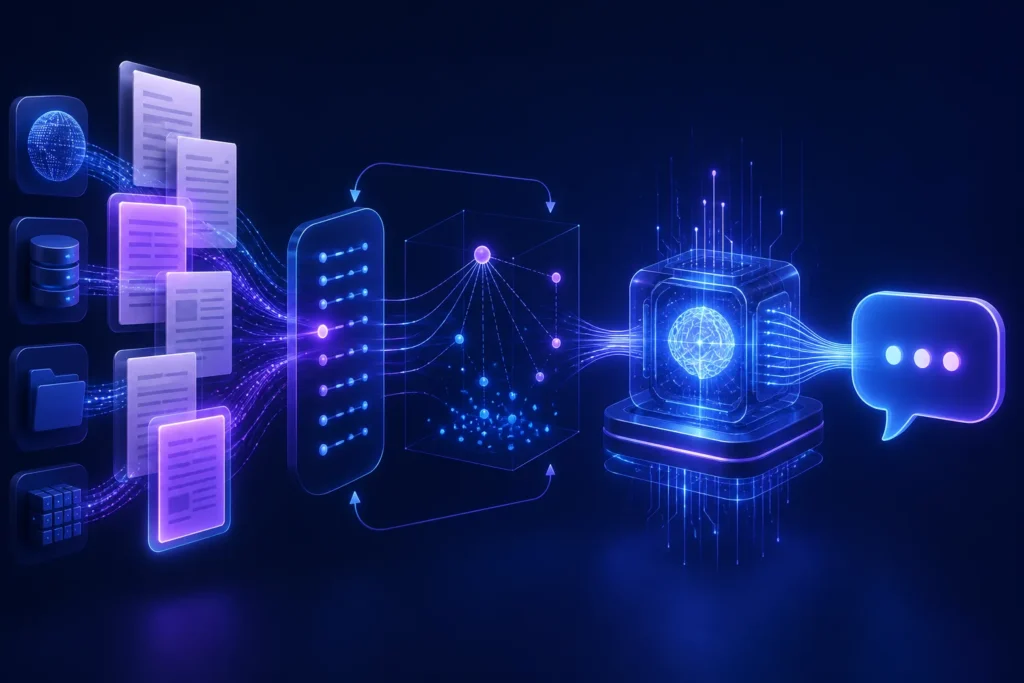
A retrieval-augmented generation chatbot identifies source sections relevant to a user query and inserts those sections into the conversation. The model can then generate an informed response from passages appended to its input text.
Embeddings are lists of numbers that represent the meaning of content. A search workflow stores document embeddings, creates an embedding for the user’s query, and compares the vectors for closeness. That makes retrieval a separate step from generation: the system first selects evidence, then supplies it to the language model.
RAG Chatbot Mistakes That Lead to Wrong Answers often begin before the model writes anything. RAG Chatbot Mistakes That Lead to Wrong Answers can also reflect weak search context. For a business planning a custom AI chatbot or RAG knowledge system, use AI Build Desk to organise the pipeline from source preparation through retrieval, prompting, evaluation, and handoff. Treat RAG Chatbot Mistakes That Lead to Wrong Answers as a process problem to isolate stage by stage.
Which errors in document preparation, chunking, or metadata cause a RAG chatbot to retrieve irrelevant or incomplete information?
Document preparation affects whether a retrieved passage is focused, complete, and current. Good segmentation aims for relatively self-contained pieces about a specific topic or chapter. Systems generally embed and retrieve chunks rather than whole documents so retrieval can be more precise and the text can fit downstream systems.
Mixed-topic chunks can create blurred vectors, while overly large chunks dilute meaning and overly small chunks lose disambiguating context. Fixed-size splitting can separate a menu item’s name, price, description, and dietary information, making a complete answer harder to retrieve. Semantic chunking follows logical boundaries instead of character counts, and a Markdown heading for each menu item can keep its details together.
Metadata such as source, permissions, timestamps, and document identifiers can reduce retrieval noise through filters. Stale knowledge-base content can still be presented as current truth. RAG Chatbot Mistakes That Lead to Wrong Answers, RAG Chatbot Mistakes That Lead to Wrong Answers, and RAG Chatbot Mistakes That Lead to Wrong Answers can therefore arise from structure, filtering, or freshness.
How do embedding-model choice, similarity search, and the top-k setting affect the accuracy of retrieved passages?
Embedding-model choice determines how document and query meaning is represented for search. The query should use the same model as the documents so both vectors occupy a comparable space and their distances can be compared. Approximate nearest-neighbor search trades perfect recall for speed, while top-k search returns the k chunks most similar to the query.
A general embedding model may group concepts broadly and miss specialised distinctions. Semantically similar documents can also be contextually irrelevant, diluting relevance. Hybrid lexical and semantic search with product filters can preserve conceptual recall while reducing cross-product drift.
Configuration options include domain terminology support, sparse embeddings, temporal metadata filters, and retrieval across multiple document granularities. RAG Chatbot Mistakes That Lead to Wrong Answers can follow from any of these choices. RAG Chatbot Mistakes That Lead to Wrong Answers are easier to investigate when model, index, filters, and top-k are recorded. RAG Chatbot Mistakes That Lead to Wrong Answers shouldn't be blamed on generation before retrieval is checked.
What prompt and context-management mistakes cause a RAG chatbot to ignore evidence or invent unsupported details?
Long conversations consume context-window capacity through accumulated user messages and prior model responses. Source removal can free space by removing material that is no longer actively referenced and focusing the conversation on relevant information.
A clear evidence boundary matters. An example system prompt instructs the model to answer based only on the provided context. Context poisoning occurs when compromised, outdated, or irrelevant information enters the context window and degrades responses. Corrupted information can then propagate into an answer, where the language model may reference it as truth.
Context overflow can overwhelm attention to important evidence, causing relevant information to disappear from the answer. RAG Chatbot Mistakes That Lead to Wrong Answers may therefore reflect conversation history rather than retrieval alone. RAG Chatbot Mistakes That Lead to Wrong Answers can also reflect an unclear evidence boundary. Check both before changing the model. RAG Chatbot Mistakes That Lead to Wrong Answers become more diagnosable when you log the supplied context.
How can retrieval precision, recall, and answer-grounding metrics help identify the source of wrong answers?
Retrieval and answer grounding measure different failure points. Context Precision measures the relevant share of retrieved context while accounting for each chunk’s rank. Chunk Relevance is a binary chunk-level measure; if no retrieved chunk is relevant, retrieval has failed for that query.
Grounding checks compare a response that cites sources with those cited sources and judge whether the answer is supported. That separation helps you distinguish missing evidence from unsupported generation. A response can have relevant retrieval but still make claims that the retrieved passages do not support.
Monitoring can include relevance-score distributions, temporal patterns in retrieved results, and user-feedback signals. RAG Chatbot Mistakes That Lead to Wrong Answers are easier to locate when retrieval metrics and grounding checks are reported separately. RAG Chatbot Mistakes That Lead to Wrong Answers may indicate poor candidate selection when context relevance is low. RAG Chatbot Mistakes That Lead to Wrong Answers may instead indicate generation problems when retrieval is relevant but support is weak.
What steps can teams use to diagnose RAG Chatbot Mistakes That Lead to Wrong Answers, including when the chatbot should abstain?
Teams should evaluate retrieval and ranking separately to distinguish candidate-generation, reranking, chunking, and filtering problems. Sweep configurations while keeping chunking and the language model constant; low Chunk Relevance across multiple embedding models points toward chunking, missing metadata, or a knowledge-corpus gap.
Relative-time range filters can prioritise recent content when information changes frequently. Narrower evaluation tasks can align better with human evaluations, so test retrieval, support, and compliance as separate questions. If a user urgently needs professional intervention, the chatbot should refrain from direct help and refer the user to an appropriate emergency contact.
For RAG Chatbot Mistakes That Lead to Wrong Answers, use a checklist: inspect chunks, verify metadata, compare embedding models, test ranking, review grounding, and define abstention rules. RAG Chatbot Mistakes That Lead to Wrong Answers should be assigned to a pipeline stage, not treated as one undifferentiated defect. RAG Chatbot Mistakes That Lead to Wrong Answers can be reviewed with AI Build Desk when you prepare or repair a custom AI chatbot.
How do reranking, larger context windows, and more retrieved passages trade off answer quality against latency and cost?
Search effort can improve recall while increasing query cost, so index parameters should be tuned against service-level targets. Too few retrieved results can produce incomplete answers, while too many can cause the language model to miss key facts. More advanced NLP-based chunking can also require more computation.
Reranking is useful for complex or high-priority queries when precision matters because it can reorder results using semantic understanding of queries and documents. LLM-based reranking can address constraints that embeddings may miss, such as excluding external dependencies. A lighter model can perform preliminary screening when the primary model is computationally expensive.
RAG Chatbot Mistakes That Lead to Wrong Answers aren't solved by maximising one setting. RAG Chatbot Mistakes That Lead to Wrong Answers should be assessed against latency, cost, context size, reranking, and retrieval count together. RAG Chatbot Mistakes That Lead to Wrong Answers are practical design problems, so choose settings for the application you need to operate.
What should teams test after fixing a RAG chatbot to check whether wrong answers have been reduced without harming correct answers?
A useful experiment runs questions and logs every answer, retrieved chunk, and evaluator score for each configuration. Compare results before and after a change: unsupported answers should decrease while response quality stays stable or improves. Test retrieval, grounding, compliance, specificity, abstention, latency, and cost together before deployment.
Compliance can vary sharply with a control: 81% of responses had an acceptable compliance score with a critical analysis filter enabled, compared with 8.3% when it was disabled. Targeted specificity testing also matters. Across schizophrenia questions, a filter flagged two responses, and most raters agreed with both criticisms.
RAG Chatbot Mistakes That Lead to Wrong Answers should be measured against correct answers as well as failures. RAG Chatbot Mistakes That Lead to Wrong Answers can fall while another quality measure worsens, so use before-and-after evidence. RAG Chatbot Mistakes That Lead to Wrong Answers are a practical brief for AI Build Desk: ask the team to prepare a RAG knowledge-system brief or help evaluate an AI development partner.
| Chunk size/type | Stated characteristic or use |
|---|---|
| Smaller chunks | offer more granularity but may lose context |
| 64–128-token chunks | suit concise, fact-based answers |
| Larger chunks | preserve more context but reduce retrieval precision |
| 512–1024-token chunks | work better for broad or technical questions |
Key Takeaways
- Inspect chunk boundaries, metadata, and stale content before blaming generation.
- Use the same embedding model for documents and queries, then evaluate top-k and ranking choices.
- Separate retrieval metrics from answer-grounding checks to locate the failure stage.
- Define evidence boundaries and abstention rules before deployment.
- Run before-and-after tests that track quality, compliance, specificity, latency, and cost.
Frequently Asked Questions
How does a RAG chatbot use retrieved documents?
A RAG chatbot retrieves relevant document sections, appends those passages to a language model’s input, and generates a response from that context.
What causes a RAG chatbot to retrieve irrelevant information?
Chunking errors include mixed-topic, overly large, and overly small chunks, while stale content can still be presented as current truth.
How do embeddings and top-k affect RAG accuracy?
Document and query embeddings should use the same model, and vector search returns the top k chunks most similar to the query.
How can prompts reduce unsupported RAG answers?
A prompt can instruct the model to answer only from provided context, while source removal can free context space for actively relevant information.
Which metrics help diagnose RAG retrieval problems?
Context Precision measures the relevant share of retrieved context while accounting for chunk rank, and Chunk Relevance treats each chunk as relevant or not relevant.
When should a RAG chatbot abstain?
A chatbot should abstain and refer a user to an appropriate emergency contact when the user urgently needs professional intervention.
How do retrieval depth and reranking affect RAG cost?
More search effort can increase recall but also increase query cost, while too many retrieved results can cause the language model to miss key facts.
How should you test a repaired RAG chatbot?
A useful test runs questions and logs each answer, retrieved chunks, and evaluator scores for every configuration.